Projects
Spatially Aware Machine Learning for Cell Classification in Spatial Transcriptomics
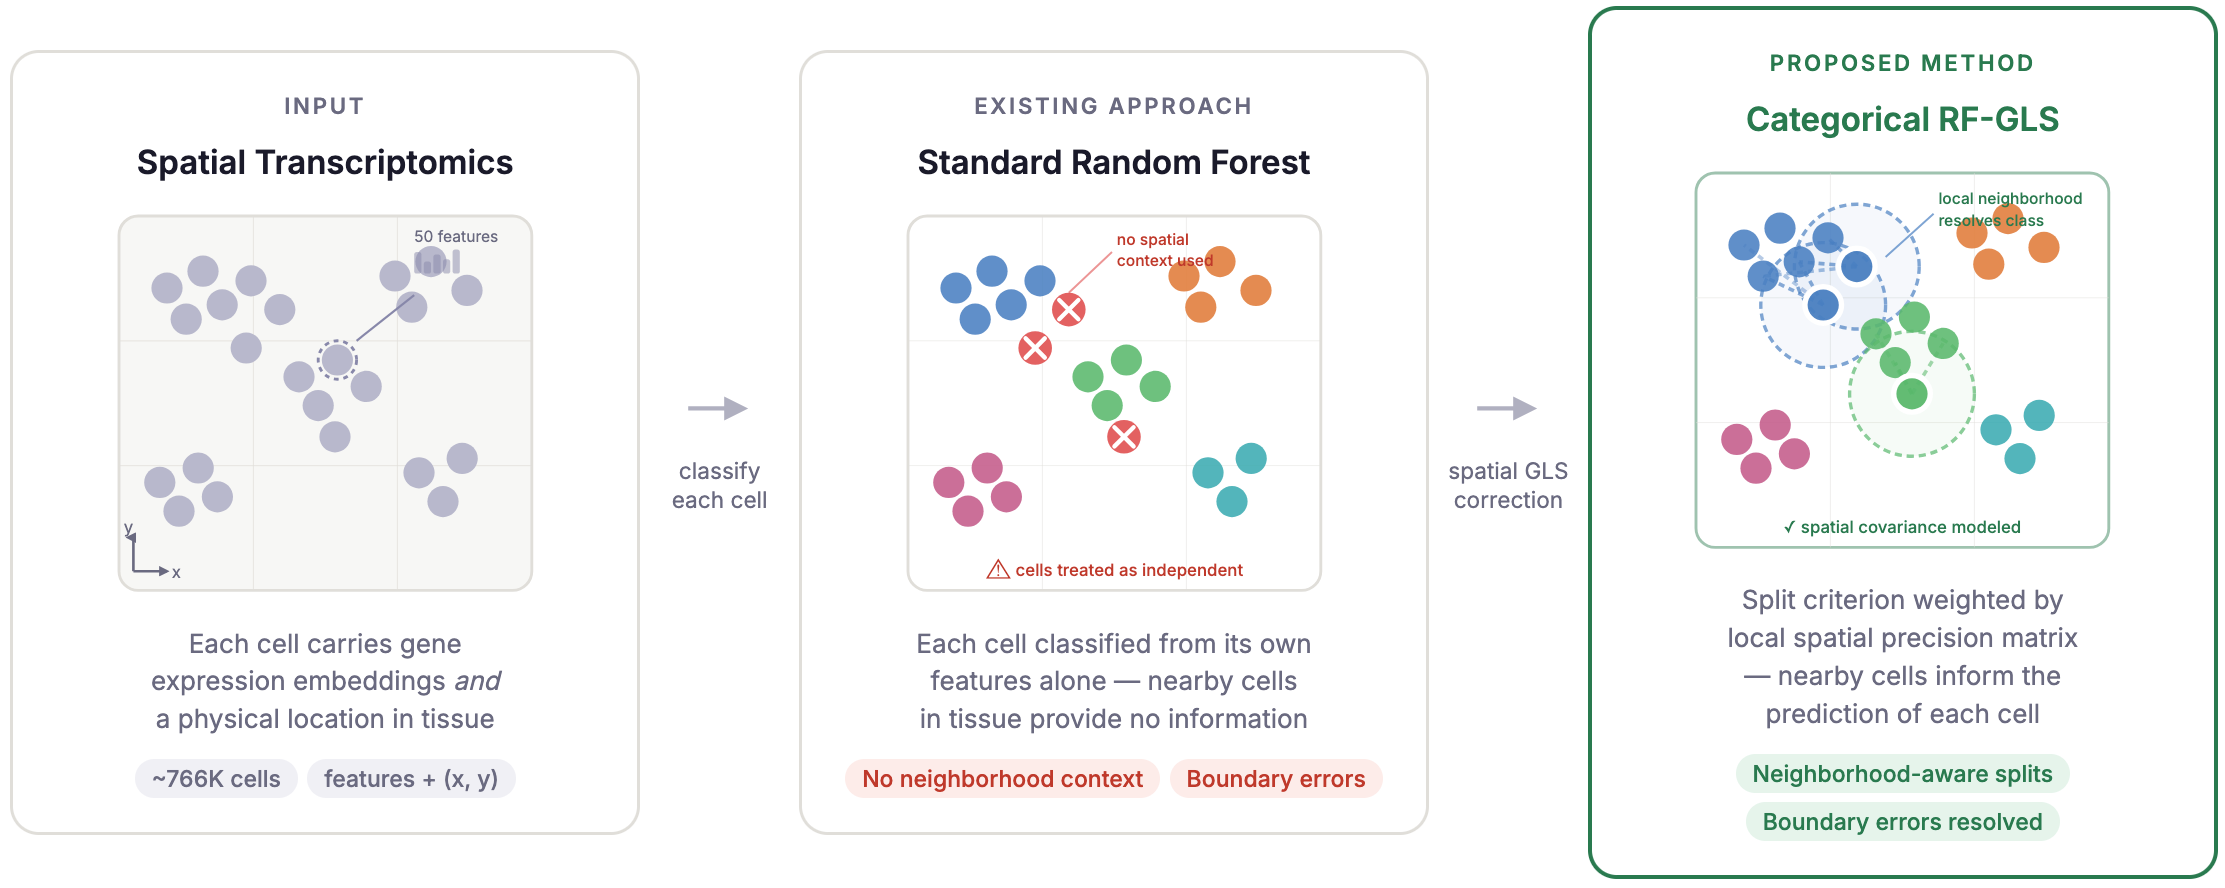
This research works on developing a novel extension of spatially-aware machine learning methods to multi-class classification problems, applied to spatial transcriptomics data from vesicant-exposed skin tissue. Vesicants are chemical agents that cause severe cellular damage. Understanding which cell types are most affected and how that damage evolves over time requires statistical methods that can classify hundreds of thousands of individual cells accurately while accounting for the fact that nearby cells in tissue are not independent observations. This work addresses a genuine gap in the existing literature by incorporating spatial correlation structure directly into the classification framework, moving beyond the independence assumption that standard methods rely on. The preliminary results are promising, and the methodological contribution extends well beyond this application to any classification problem where observations are spatially or otherwise correlated.
Calibrated test-time guidance for Bayesian inference
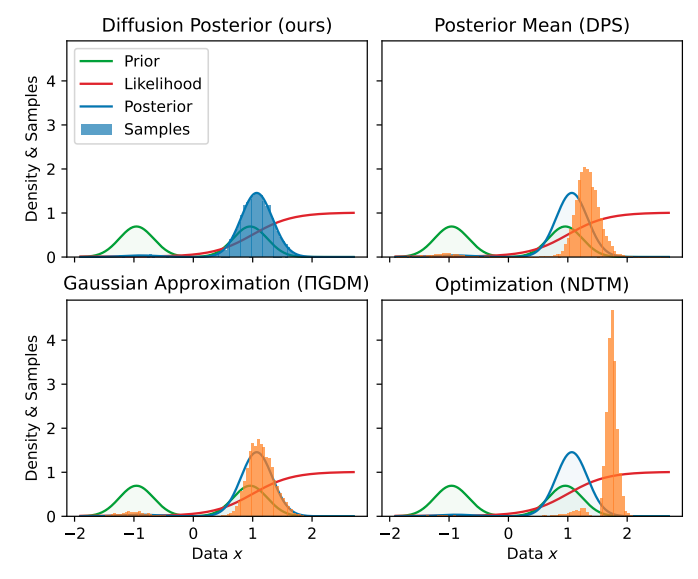
Test-time guidance is a widely used mechanism for steering pretrained diffusion models toward outcomes specified by a reward function. Existing approaches, however, focus on maximizing reward rather than sampling from the true Bayesian posterior, leading to miscalibrated inference. This project shows that common test-time guidance methods do not recover the correct posterior distribution and identify the structural approximations responsible for this failure. It then proposes consistent alternative estimators that enable calibrated sampling from the Bayesian posterior. This method has many applications across scientific domains, where calibration is more important than reward maximization.
Integrating Electronic Health Records for Prediction and Causal Inference
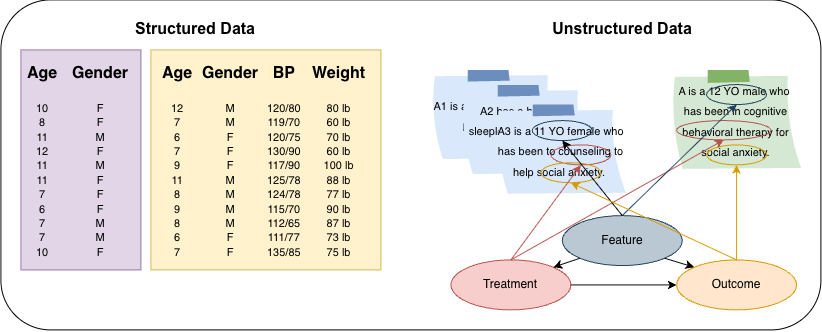
Electronic health records (EHRs) contain rich, comprehensive information about patient health. They consist of multiple high-dimensional, heterogeneous, and multimodal datasets that may include both structured information (e.g., demographics and vital signs) and unstructured information (e.g., clinical notes). This wealth of data provides valuable opportunities for medical professionals and researchers to improve diagnostic accuracy, develop personalized treatment strategies, and identify causal relationships that can inform clinical decision-making. However, rigorously integrating these heterogeneous data sources and drawing valid predictions and causal inferences present significant statistical challenges. This project aims to bridge the gaps in current research by developing statistically grounded methods for analyzing clinical data that can be further extended to other domains with complex data.
HelixCardia: Minimally Invasive Cardiac Support Through Natural Helical Motion
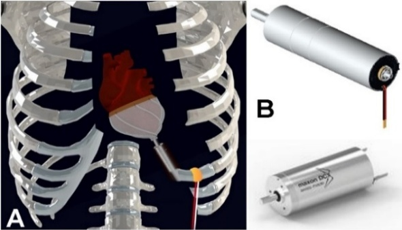
Heart failure affects over six million adults in the U.S., with approximately 200,000 patients reaching end stage. Scarce donors and comorbidities restrict heart transplants, and current ventricular assist devices are invasive, with risk of long-term complications. HelixCardia is a minimally invasive option that directly contours over the outer surface of both ventricles and produces a natural helical motion to bolster cardiac function. The device is designed around native cardiac biomechanics and is wirelessly powered (6.78 MHz RF) through a multi-coil architecture.
Causal Mediation Analysis of Carbohydrate Intake and Insulin on Postprandial Glycemia
Mobile health (mHealth) which uses digital devices to collect real-time data and deliver health care interventions, has emerged as accessible tools to support various health behaviors, including continuous glucose monitoring, physical activity tracking, and mental health management. Careful analysis of mHealth data has the potential to provide improved and individualized care for patients. However, the high frequency, longitudinal scope, and multi-modal nature of mHealth data introduce unique methodological challenges, complicating analysis and the extraction of actionable insights. This research aims to integrate statistical theory with deep learning techniques to address these challenges and ultimately provide practitioners with precise and interpretable results.

Machine Learning for Multimodal Modeling and Early Detection of Alzheimer’s Disease
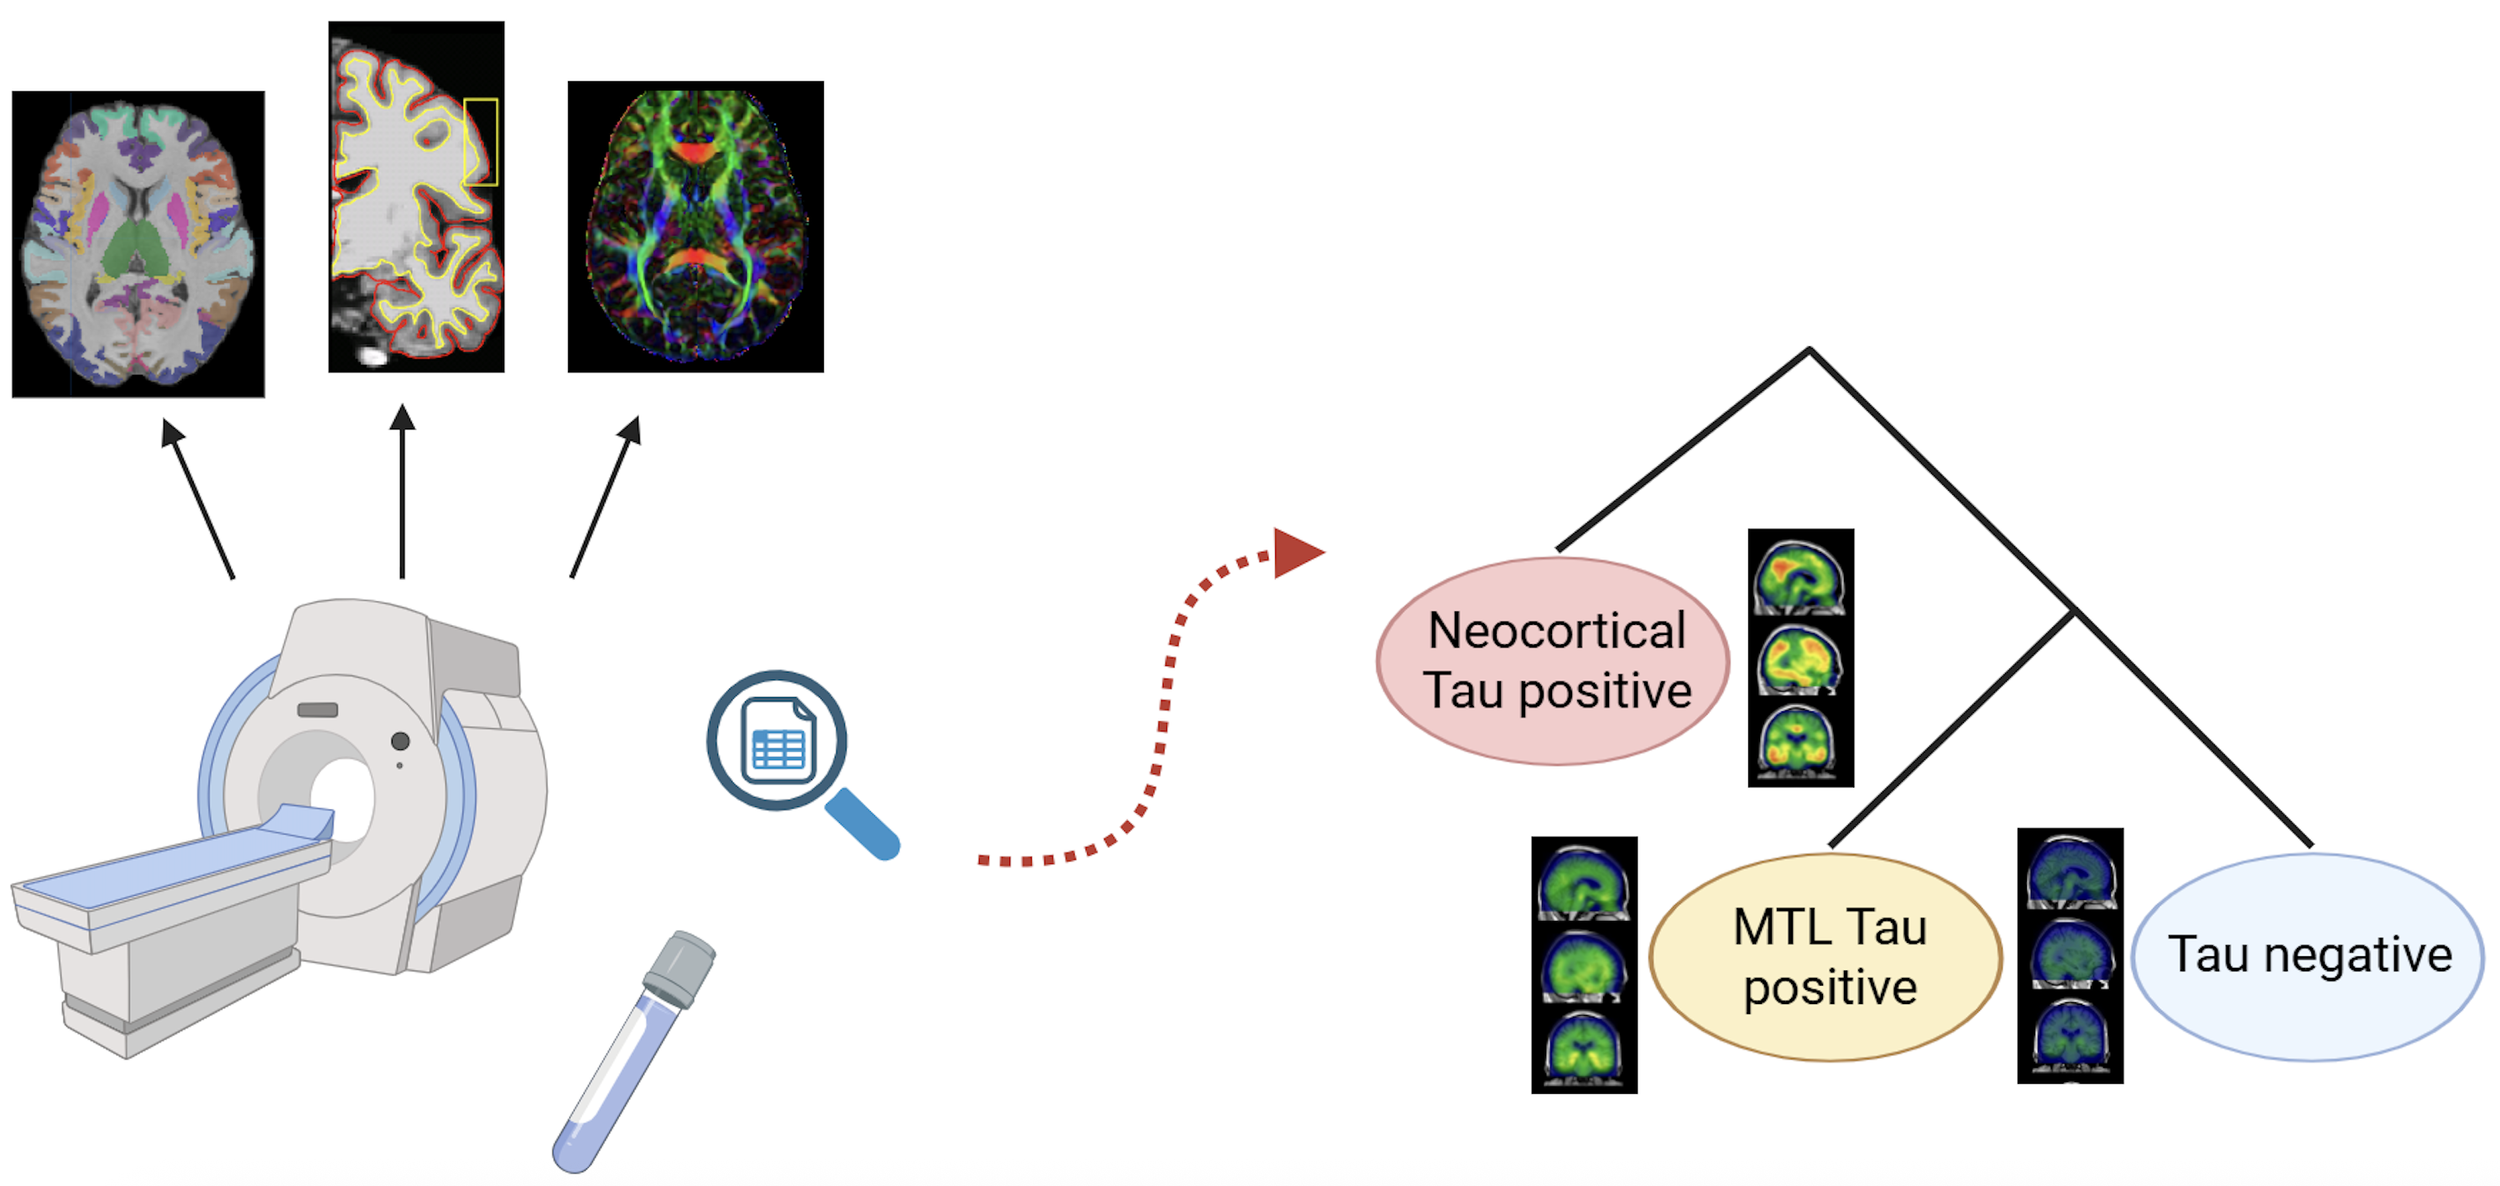
This research aims to develop interpretable and generalizable machine learning models that integrate neuroimaging, biomarker, and cognitive data to enhance the early detection and understanding of Alzheimer’s disease (AD). The first component focuses on modeling redundancy in diffusion-weighted imaging (DWI) metrics by utilizing statistical and unsupervised learning techniques to identify an optimized set of diffusion metrics. A second project expands early detection efforts by constructing a temporal event-based model to identify the order of decline across multiple cognitive domains during AD progression. Finally, a third project aims to predict regional tau PET burden using more accessible data sources such as structural MRI, DWI, and plasma biomarkers.
Overcoming Antibiotic Resistance through Data-Driven Phage Cocktail Design for Evolution-Proof Therapies
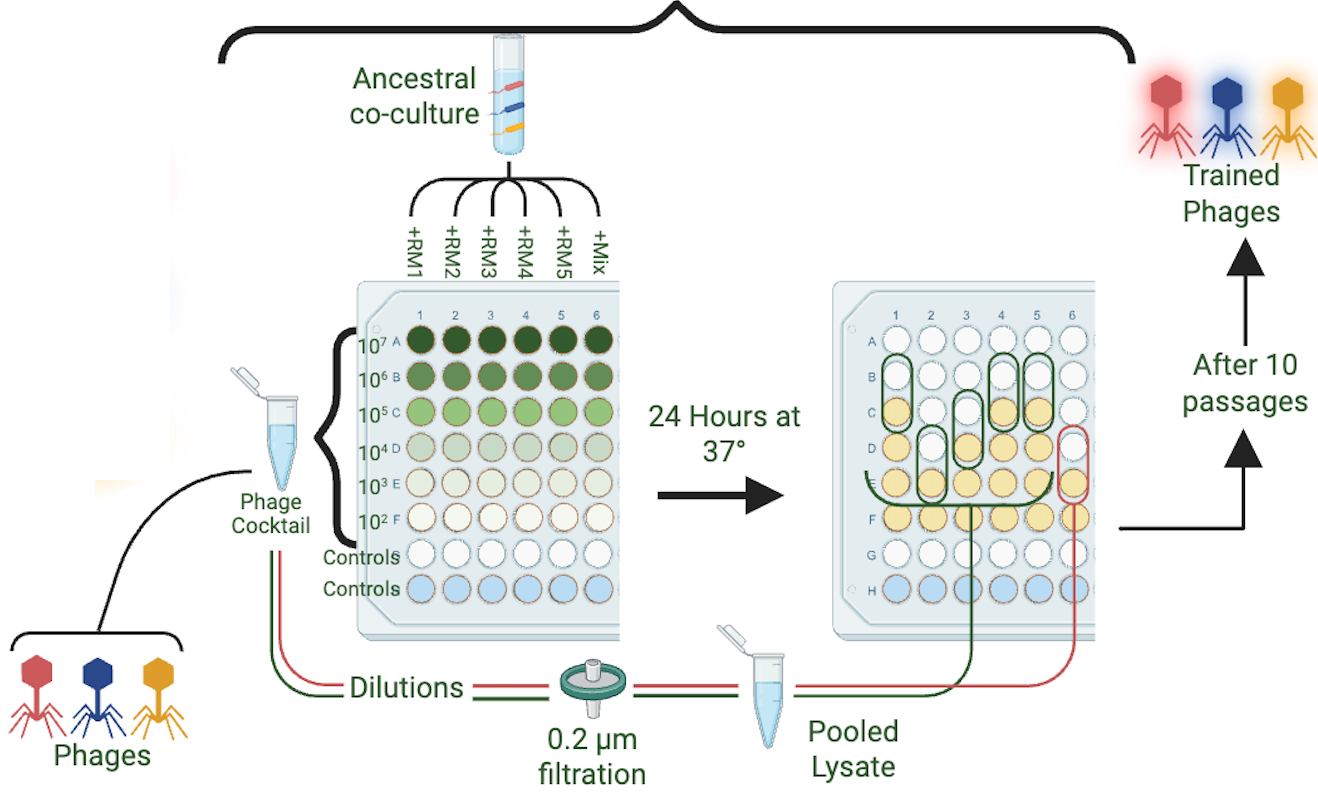
This research addresses the antimicrobial resistance crisis through the design of advanced therapeutic phage cocktails. We combine statistical modeling with directed evolution to design and assess phage cocktails with broad host ranges and minimized likelihood of bacterial resistance. By combining genetic changes in bacteria and phages with phenotypic outcomes like fitness, host range, and resistance suppression into a framework called CAPE (Cocktail Analysis and Predicted Evolution), this research aims to transform phage cocktail design from trial-and-error to a rigorous, evolution-informed process. Ultimately, bring phage therapy into the 21st century, and use nature’s perfect predator to tackle the antibiotic resistance crisis head-on.

Joint False Discovery Rate Control for Correlated High-Dimensional Genomic Data
This research focuses on developing and applying statistical methods to improve inference from high-dimensional biological data. The goal is to develop statistical models that enable more powerful procedures for multiple testing in genomics, with an overarching aim of creating robust methods that account for dependencies across data sources. Typically, in large-scale genomics studies thousands of hypotheses are tested simultaneously, often across related conditions. Standard false discovery rate (FDR) procedures typically treat each condition independently, which can reduce power and obscure true signals. This research develops a joint FDR framework that explicitly models correlation between test statistics across conditions. Simulations and applications to mouse astrocyte gene expression data show that the joint approach improves sensitivity while maintaining FDR control, uncovering significant genes missed by univariate methods.